There's a real tension in early-stage SaaS architecture: over-engineering for scale you don't have yet wastes time you desperately need for finding product-market fit, but ignoring scale entirely creates expensive rebuilds right when growth finally shows up. The actual skill is knowing which decisions are cheap to make right now and expensive to fix later, versus which ones can genuinely wait.
The decisions worth getting right before you have users
Your data model, especially multi-tenancy. If you're building anything used by more than one organization or team, decide how tenant data will be isolated before you write your first migration. Retrofitting this after real data exists is one of the most expensive architecture mistakes to fix, involving live data migration with real risk of corruption or downtime.
Authentication and authorization structure. Not the specific provider, that's swappable, but the underlying model: are permissions role-based, relationship-based, resource-based? This shapes your schema and your application logic pervasively enough that changing the model later touches nearly every feature you've built.
How files and large data get stored. Deciding early that files live in object storage like S3, not your application database or server disk, avoids a genuinely painful migration once you have real user-generated content and no easy way to move it without downtime.
Your approach to background jobs and async work. Even if you don't need a sophisticated job queue on day one, deciding that certain operations, sending emails, processing uploads, generating reports, run asynchronously rather than blocking a request, is a pattern that's far easier to establish from the start than to retrofit once synchronous code is scattered throughout your codebase.
The decisions that can genuinely wait
Specific caching infrastructure. As covered in my Redis versus database caching piece, most early-stage products don't need Redis on day one. Optimize your queries first, add dedicated caching infrastructure when actual usage data tells you where it's needed.
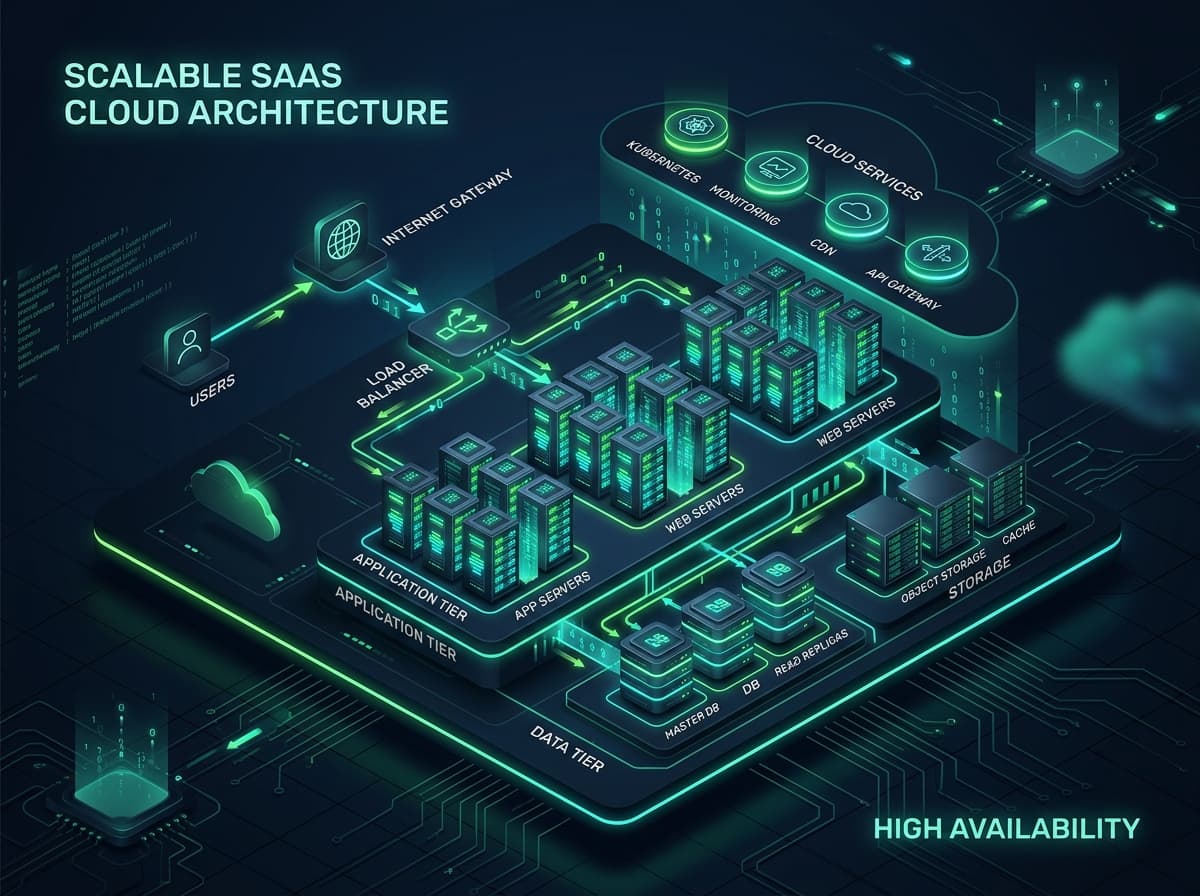
Microservices versus a monolith. Early-stage products almost always benefit from starting as a well-organized monolith. Splitting into services before you understand your actual scaling bottlenecks adds operational complexity without a corresponding benefit, and the boundaries you'd guess at now are usually wrong anyway.
Advanced database sharding or read replicas. These solve problems you don't have yet at low user counts. A single well-indexed database instance handles far more load than most founders assume, often into the tens of thousands of users, especially combined with basic caching once genuinely needed.
Kubernetes or complex container orchestration. Unless you already have the operational expertise on your team, a simpler deployment model, a managed platform or a straightforward container setup, gets you to your first real users faster, with the migration to more complex infrastructure deferred until scale actually demands it.
The mental model that actually helps
Ask, for each architecture decision: is this cheap to change later, or does it touch data that will exist by the time I need to change it? Decisions touching your core data model and how data gets isolated between tenants are expensive to change later, because changing them means migrating real, live data. Decisions about infrastructure and tooling, caching layers, deployment platforms, are comparatively cheap to change later, because they don't require touching the shape of your actual data.
Spend your early architecture time on the first category. Defer decisions in the second category until real usage data tells you what you actually need.
A mistake worth naming directly
I've seen founders spend weeks designing a horizontally scalable, multi-region architecture for a product with zero paying users, while their actual data model had no coherent multi-tenancy strategy at all. That's optimizing for a scale problem they didn't have yet, while ignoring the one architecture decision that would have been genuinely expensive to fix once real customer data existed.
What I actually do when architecting a new SaaS product
Get the data model, tenant isolation approach, and authorization structure right early, deliberately, even if it takes a bit more upfront thought. Everything else, deployment complexity, caching, background job infrastructure, gets built simply first and evolved based on actual measured needs as the product grows. This isn't a compromise. It's the correct allocation of early-stage engineering effort.
The bottom line
You don't need to build for a million users on day one. You need to avoid building yourself into a corner on the handful of decisions that are genuinely expensive to unwind once real data exists. Get those right early, keep everything else simple, and let actual growth, not speculation, tell you when it's time to add complexity.
Suggested internal links: Link to Day 13's multi-tenant architecture article, Day 5's Redis caching piece, and Day 8's AWS S3 guide.
CTA: Architecting a new SaaS product and want a second set of eyes before you build? Book a free architecture review.