
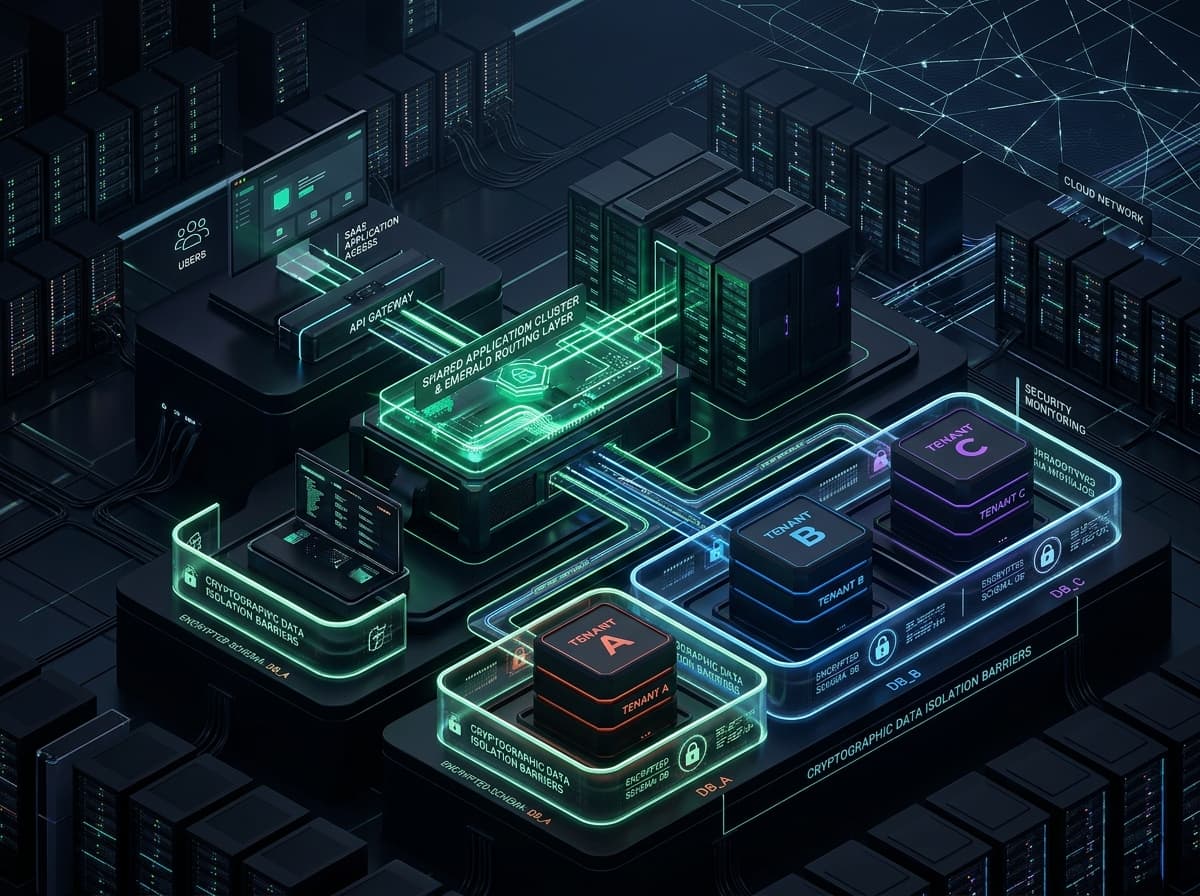
Multi-tenancy sounds like a solved problem until you're the one deciding how tenant data actually gets isolated inside your schema. I made a set of real architecture decisions building a multi-tenant SaaS platform for a client, and I want to walk through the reasoning, including the parts I'd reconsider.
For context: this was a platform I architected and built for a client's business, not something I own myself. That context shaped several decisions, because the risk tolerance for someone else's client data is different from what I'd choose on my own product.
The first real decision: how to isolate tenant data
There are three common approaches to multi-tenant data isolation, and each has a real tradeoff:
Separate databases per tenant. The strongest isolation, each tenant's data physically separated. Best for compliance-heavy industries, but operationally expensive to manage at scale, migrations and backups multiply with every new tenant.
Shared database, separate schemas. A middle ground, one database instance, but each tenant gets their own schema. Reasonable isolation with less operational overhead than fully separate databases, though still more complex to manage than a single shared schema.
Shared database, shared schema, tenant ID column. The simplest to build and scale operationally, every table includes a tenant identifier, and application-level logic enforces isolation. The tradeoff is that isolation now depends on your application code being correct every single time, not on the database structure itself.
For this client, handling advisory work involving sensitive financial and legal information, I chose shared database, shared schema, with a strict tenant ID enforced at the query layer, backed by row-level security policies at the database level as a second line of defense. Pure application-level enforcement felt too risky for the sensitivity of the data. The database-level policy meant a bug in application logic couldn't accidentally leak one tenant's data to another, because the database itself would refuse the query.
Why not separate databases per tenant, given the sensitivity
I considered it seriously. The operational cost won out against the marginal security gain, given that row-level security policies at the database level already provided strong isolation without the overhead of managing dozens or eventually hundreds of separate database instances. Separate databases made more sense for a product anticipating a handful of very large enterprise tenants. This client anticipated many smaller advisory practices, where the operational overhead of separate databases per tenant would have outpaced the benefit.
The permissions layer, and why it changed mid-build
I mentioned in an earlier piece that the client's permission requirements changed significantly once they saw an early version of the system, specifically around advisors covering for each other. This forced a real architecture decision: was permission checking going to live purely in application code, or did it need to be modeled more explicitly in the data layer?
I moved toward an explicit permissions table modeling relationships between advisors and clients, rather than hardcoding role checks in application logic. This was more work upfront but made the mid-project pivot to advisor coverage dramatically easier to implement, because the permission model was already designed to represent relationships, not just fixed roles.
What I'd do the same way again
Row-level security at the database level, for handling sensitive data. It added upfront complexity but meant the worst-case failure mode, a tenant data leak from an application bug, was defended against at a layer the application code couldn't accidentally bypass.
What I'd reconsider
I underestimated how much the permissions model would need to flex early on. If I were starting this project again, I'd model relationships between users more explicitly from day one, rather than starting with simpler role-based checks and refactoring once the real requirement surfaced. That refactor was manageable because of the underlying schema decisions, but it would have been cheaper to avoid entirely with more upfront modeling.
The bottom line
Multi-tenant architecture decisions aren't abstract technical exercises, they're a direct reflection of how much risk the underlying data can tolerate. For sensitive client data, I'll choose the more defensible, database-enforced isolation approach over the simplest one every time, even when it costs more upfront engineering effort. That tradeoff has never once felt like the wrong call in hindsight.
Suggested internal links: Link to Day 6's custom SaaS process article and Day 20's scalable SaaS architecture piece.
CTA: Architecting a multi-tenant product and want a second opinion? Book a free architecture review.