
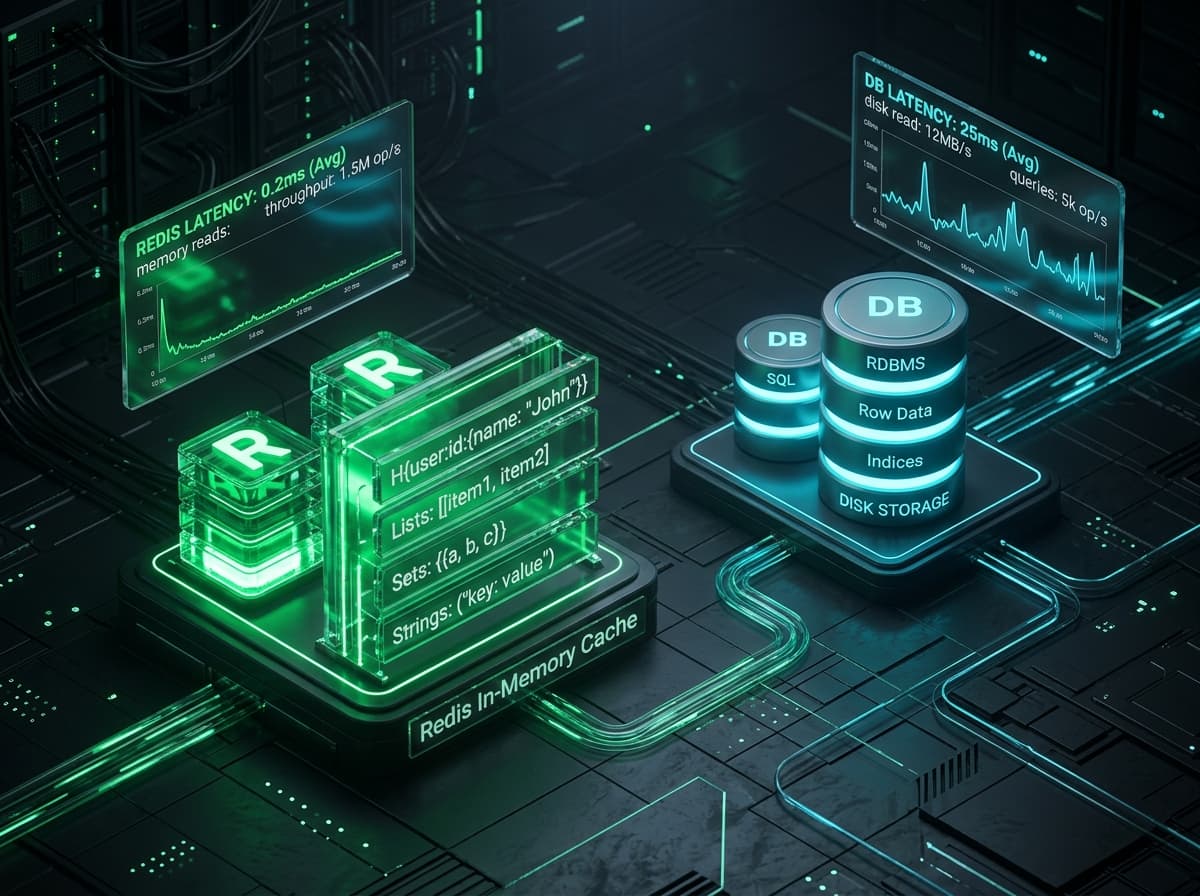
Somewhere along the way, "add Redis" became the default answer to every performance question in SaaS. It's not wrong often enough that people question it. It is, however, wrong often enough that I want to walk through when it actually earns its place versus when database-level caching does the job just as well for a fraction of the operational overhead.
What each option actually is
Database caching means letting your database do what it's already built to do: query result caching, indexed lookups, materialized views, connection pooling. No new service, no new infrastructure to monitor, no new failure mode.
Redis is a separate in-memory data store sitting in front of or alongside your database, purpose-built for extremely fast reads and writes, but it's a service you now have to run, monitor, secure, and pay for.
They solve overlapping problems, but they're not interchangeable, and picking one over the other has real cost and complexity implications.
When database caching is genuinely enough
- Read-heavy queries on stable data. If a dashboard query runs the same shape of lookup for thousands of users and the underlying data doesn't change every second, a well-indexed query plus your database's own query cache handles this fine.
- Low request volume. Early-stage SaaS products with a few hundred active users rarely need Redis's raw speed. A slightly slower query at low volume is invisible to users. The engineering time saved not managing Redis is worth more than the milliseconds saved.
- Simplicity is a feature, not a shortcut. Every service you add is something that can go down. For a solo founder or small team, one less moving part is a genuine architectural win, not just laziness.
When Redis actually earns its place
- Session storage at scale. If you're managing sessions for a meaningfully sized user base across multiple app server instances, Redis's speed and shared-state model solves a real problem database queries handle poorly.
- Rate limiting and counters. Redis's atomic increment operations are close to purpose-built for this. Trying to do accurate rate limiting through database rows invites race conditions you don't want to debug at 2am.
- Frequently changing, expensive-to-compute data. Leaderboards, real-time aggregates, anything recalculated often and expensive to query fresh each time. This is Redis's actual home turf.
- Pub/sub for real-time features. If you're building notifications or live updates alongside a WebSocket layer, Redis's pub/sub capability does double duty as both cache and messaging layer.
The mistake I see most often
Founders add Redis before they've optimized their actual queries. I've walked into codebases where a slow endpoint got "fixed" by caching its output in Redis, when the real problem was a missing database index that would have solved it with zero new infrastructure.
Caching a slow query doesn't fix the query. It hides the problem until the cache misses, at which point you're debugging the same slow query, plus a cache invalidation bug, under more pressure.
Fix the query first. Add Redis when caching a fast query for even more speed, not to paper over a slow one.
A decision framework you can actually use
Ask these in order:
- Is the underlying query actually optimized? If not, fix that first. This alone resolves most "we need Redis" conversations.
- Does this data need to be shared across multiple servers or processes in real time? If yes, that's a real Redis use case (sessions, rate limits, pub/sub).
- Is this data expensive to compute and read far more often than it changes? If yes, Redis-based caching is justified.
- Can your current traffic volume tolerate the slightly slower database-only path? If yes, you can defer Redis until you actually need it, and you probably don't need it as early as you think.
What I actually run for clients
Most early-stage SaaS builds I architect start with well-indexed queries and no Redis at all. Redis gets introduced specifically for sessions and rate limiting once user volume justifies it, and expands from there based on actual measured bottlenecks, not assumptions.
The bottom line
Redis is a great tool solving a specific class of problem: shared, fast, frequently accessed state across multiple processes. It is not a substitute for correct database design, and adding it before you need it just gives you a second system to maintain without a matching performance win. Optimize first. Add Redis when the data, not the anxiety, tells you to.
Suggested internal links: Link back to Day 1's Next.js article and forward to Day 20's scalable SaaS architecture piece.
CTA: Need a second opinion on your stack before you scale? Book a free architecture review.